CodetoKloudCodetoKloudBook an AWS review

A Compliance-Ready On-Prem Kubernetes Platform

A technology company needed a production-grade on-premise Kubernetes platform with GPU scheduling and a complete operational handoff while preparing controls for SOC 2, HIPAA, HITRUST, and NIST 800-53.

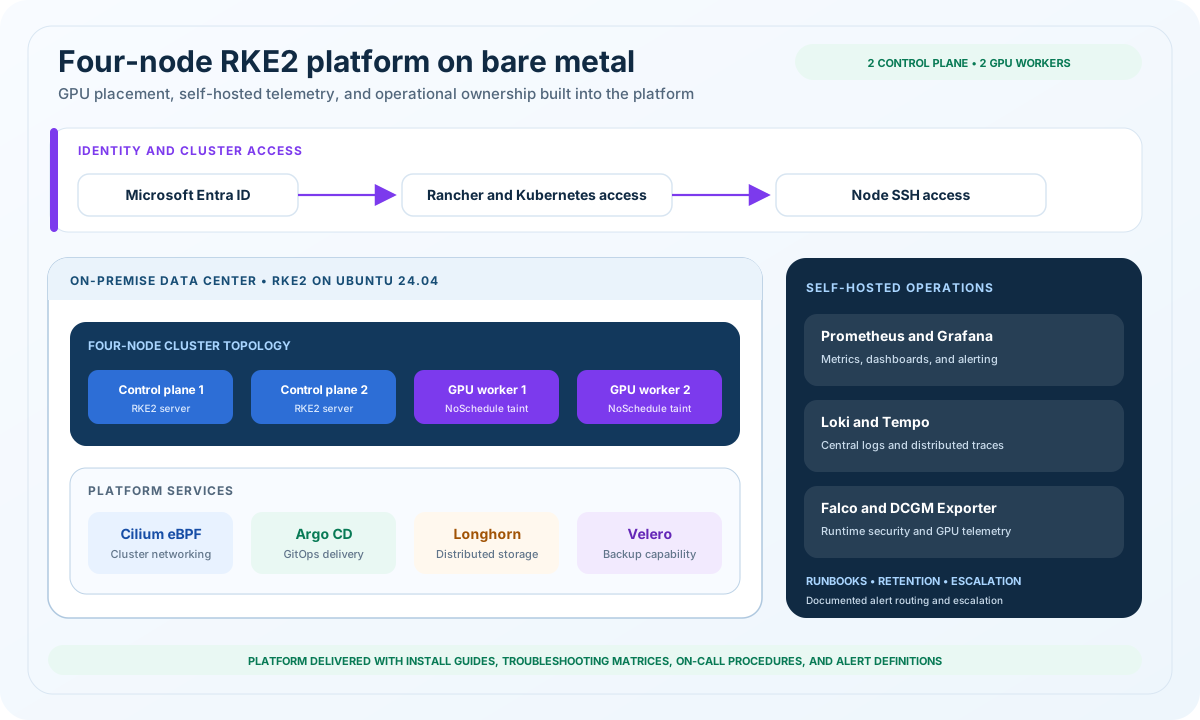
Four-node RKE2 platform with two control-plane nodes, two GPU workers, Entra ID access, GitOps, storage, backup, observability, runtime security, and documented alert escalation
AWS Advanced Tier Services PartnerAWS Advanced Tier Partner★ 4.9/5 on Clutch (9 reviews)Replies within 1 business day
4-node RKE2 platform2 GPU workersSelf-hosted observability

The Challenge

The company needed a production-grade on-premise Kubernetes platform that could schedule AI workloads across dedicated NVIDIA GPU capacity while keeping operational telemetry inside its environment.

Its internal team also needed enough documentation to install, operate, monitor, troubleshoot, and escalate issues across the platform while preparing controls for SOC 2, HIPAA, HITRUST, and NIST 800-53.

What We Built

Four-Node RKE2 Foundation

We deployed RKE2 on Ubuntu 24.04 across four bare-metal nodes: two control-plane nodes and two GPU worker nodes. Rancher provided a central cluster management interface.

Cilium Networking and GPU Placement

We installed Cilium with eBPF-based kube-proxy replacement and configured the NVIDIA GPU Operator. Node labels and NoSchedule taints kept general workloads off the GPU workers while allowing selected AI workloads to request GPU capacity.

Identity and GitOps Controls

We integrated Kubernetes access and node SSH with Microsoft Entra ID and used ArgoCD to manage desired application and platform state through Git.

Storage and Backup Services

We added Longhorn distributed storage and Velero backup capabilities so the platform team had cluster-native storage and a defined backup component in the operating model.

Self-Hosted Observability and Runtime Security

We deployed Prometheus, Alertmanager, Grafana, Loki with Promtail, Tempo, Falco, and NVIDIA DCGM Exporter inside the cluster. Node exporter, kube-state-metrics, and cAdvisor added infrastructure and workload visibility without sending the primary telemetry stack off site.

Runbooks and Alert Escalation

We delivered step-by-step installation guides, architecture documentation, component troubleshooting matrices, a data center hardware runbook, log retention guidance, dashboard definitions, alert routing, and documented escalation paths.

The Result

  • The company received a four-node RKE2 platform with two control-plane nodes and two dedicated GPU workers.
  • Self-hosted metrics, logs, traces, GPU telemetry, and runtime security events gave the team one operating view while keeping the monitoring stack on premise.
  • The internal team received install guides, architecture documentation, troubleshooting matrices, on-call procedures, and an alert escalation model for ongoing ownership.

Technology

RKE2RancherCiliumLonghornVeleroArgoCDNVIDIA GPU OperatorPrometheusAlertmanagerGrafanaLokiTempoFalcoNVIDIA DCGM ExporterEntra ID SSO

Planning a similar platform?

Share the constraint behind your cloud, delivery, Kubernetes, or compliance project. We will confirm fit and identify three useful priorities for the first conversation.

Book an AWS review